The application engineer is reading logs. The storage engineer is checking a dependency. Support has three customer reports. A manager asks for an estimate, and two responders start changing different parts of the same request path.
Everyone is doing useful work. The missing piece is a shared decision about what happens next, who performs it and how the team will know whether it helped.
Incident command supplies that coordination. IncidentRelay gives the response an operational Incident with an owner, commander, responders, stakeholders and activity history. The people running the incident turn those records into a working process.
This guide follows a fictional file-upload outage. All people, identifiers, measurements and times in the example are illustrative; they do not describe an IncidentRelay or customer outage. For the broader product model, start with Incident management in IncidentRelay.
Separate the responsibilities before assigning the names
The person receiving a page, the person owning an investigation and the person coordinating a response may be different people. IR represents those responsibilities separately, so a technical assignment can change without silently moving operational ownership.
| Responsibility | Question it answers | Useful behavior during the incident |
|---|---|---|
| Alert Group assignee | Who holds the current technical assignment or paging responsibility for this signal? | Handle the technical episode and keep source-specific observations with its group. |
| Incident assignee | Who owns the operational investigation? | Maintain accountability for the Incident and arrange an explicit ownership transfer when needed. |
| Incident Commander | Who coordinates the active response? | Set the next response objective, organize work and keep decisions and updates moving. |
| Responders | Who is doing the investigation and mitigation work? | Take a bounded task, report evidence and surface risks or blockers. |
| Stakeholders | Who needs to understand impact and progress? | Receive useful updates and provide business context without creating competing response plans. |
One person can cover several responsibilities in a small incident. Make the overlap explicit. When the same person owns the Incident and commands the response, that is an assignment decision, not a requirement that those duties always travel together.
Communications and note-taking also need named people. A team can delegate these duties to participants and record that arrangement in the Incident. This is a working agreement; it does not require inventing extra IR permission roles or assuming that a commander automatically receives administrator access.
Google's Incident Response chapter describes coordination, operational work and communications as distinct responsibilities. Apply that distinction at the scale of your team: enough separation to keep the response moving, with no requirement to assemble a committee for every warning.
Use On-call Roles to find people, then name the actual response team
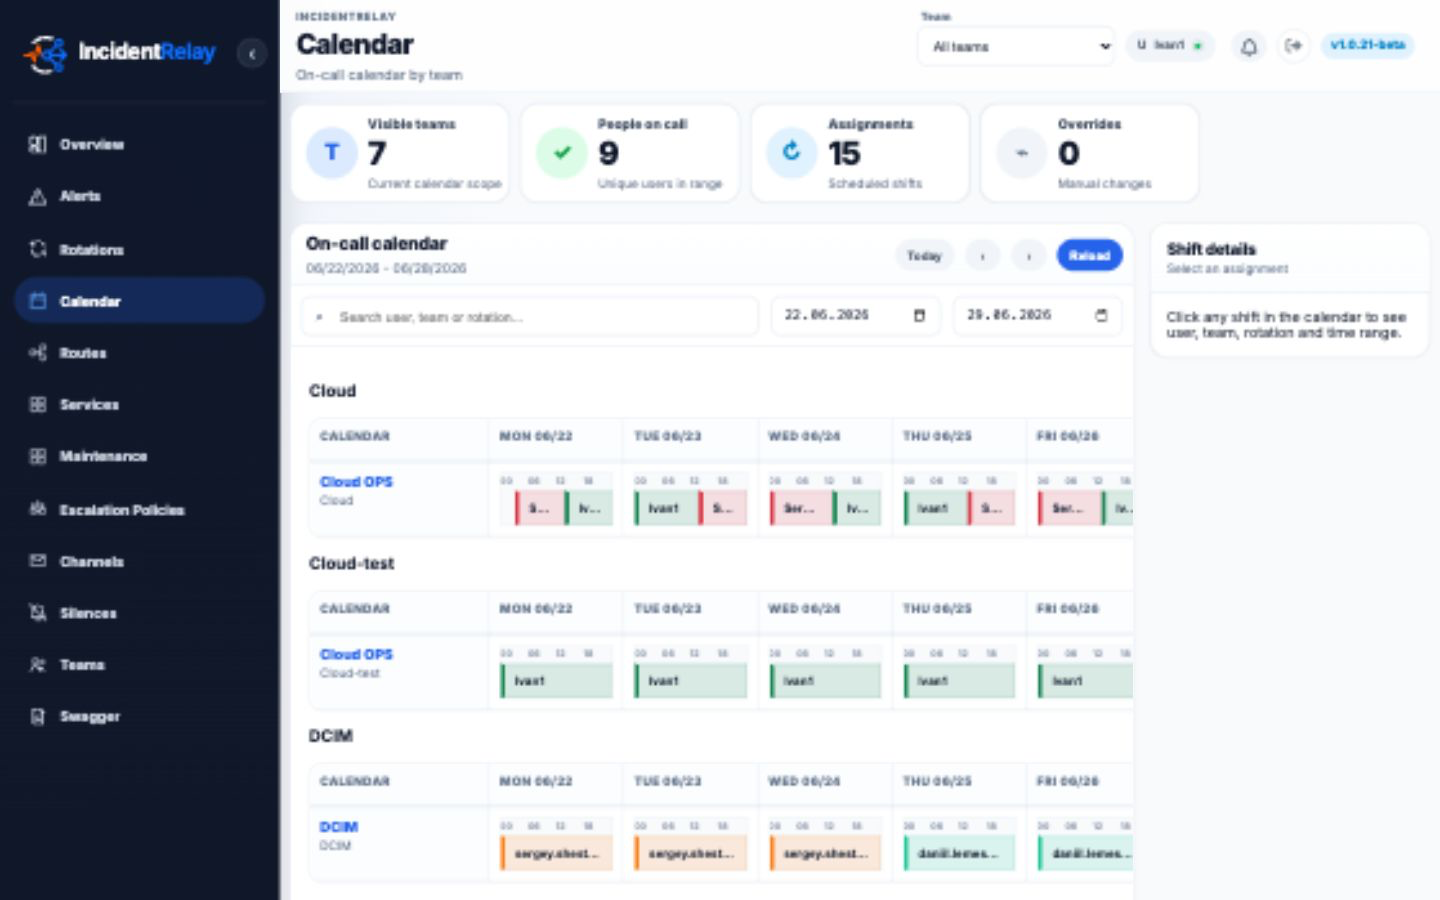
IR's On-call Roles help identify current candidates for Incident ownership, command and responder participation. The resulting Incident assignments store concrete users. They remain understandable after the schedule changes.
In our exercise, Maya owns the Incident, Leo commands the response, Priya investigates the upload API, and Anton investigates storage access. Jo handles stakeholder updates. Priya and Anton also hold the technical assignments for their respective Alert Groups.
At a rotation boundary, the next on-call engineer becomes the coverage candidate for that duty. The boundary does not silently replace Maya or Leo on the existing Incident. Changing an Alert Group assignee does not replace the Incident owner, and changing the Incident owner does not rewrite the linked groups' technical assignments.
Check that the selected people are reachable and can perform the work. If a candidate cannot participate, use the team's backup path and record the actual arrangement. A name copied from a schedule is useful context; a responder who has confirmed the task is useful capacity.
Give the first 15 minutes a few concrete outcomes
At 09:00 UTC, support reports that file uploads are failing in the EU region. Maya declares an Incident titled “EU file uploads return errors”. An upload-error group and a storage-access group are linked as evidence arrives. Their technical histories stay separate.
The following is an example response rhythm, not a product timer or a universal SLA. Move faster when impact demands it; extend a check when evidence takes longer. The purpose is to finish each interval with a clearer decision.
| Elapsed time | Coordination work | Visible outcome |
|---|---|---|
| 0–2 minutes | Confirm that coordinated response is needed, name the owner and commander, and identify the shared response channel. | Maya owns the Incident; Leo coordinates. The Incident contains the channel reference and initial impact statement. |
| 2–5 minutes | Separate confirmed impact from hypotheses and assign the first checks. | Priya checks upload failures; Anton checks storage access. Jo prepares the first stakeholder update. |
| 5–8 minutes | Compare findings and choose the next mitigation decision. | A recent configuration rollout is a supported candidate. Responders explain rollback scope and risks. |
| 8–12 minutes | Record the agreed action, who executes it, and the observations that would stop it. | Priya starts the approved rollback; Anton watches storage requests. A competing restart is held. |
| 12–15 minutes | Review the action's result, update impact and decide whether to continue investigation or monitor recovery. | The rollout is reverted and new uploads are being checked. The next stakeholder update has a named sender and time. |
At 09:05, telemetry shows 180 failed upload attempts out of 600 in the affected region over the previous five minutes: 30% of attempts, including retries. Distinct affected customers and the fate of earlier partial uploads are still unknown. That is enough to describe impact without claiming a customer count or promising that no data was lost.
Before a mitigation, define the check that will distinguish progress from activity. “The rollback job finished” establishes deployment completion. Successful new uploads, matching configuration revisions and a falling retry backlog establish different parts of service recovery.
Turn investigation requests into bounded work
A useful responder assignment includes a person, a question or action, the evidence to bring back and a check-in time. The commander records it in the operational notes and checks for a reply. An IR assignment field does not describe every investigation task on its own.
For example: “Anton, compare storage request failures before and after the configuration rollout for the EU upload service. Bring the query and any regional differences to the 09:08 check-in.” Anton can confirm the task or explain that he needs another responder with the relevant access.
At the check-in, accept a useful negative result: “No provider-wide failure is visible; the errors are limited to the upload service's requests.” Narrowing the search is progress. If the investigation is blocked, decide whether to extend it, change the question or bring in someone else.
Keep one person responsible for coordinating changes to a shared component. In the exercise, the application rollback and a proposed storage-client restart both affect the upload path. Leo asks the responders to agree on sequencing so they can attribute the result and avoid removing each other's evidence.
Responder one: “I reverted it.”
Responder two: “I restarted it.”
Commander: “We now have two changes and one very confused graph.”
Write the decision before it becomes folklore
An operational decision note should explain what the team knows, what remains uncertain and why the selected action is reasonable. Record enough context for someone joining later to understand the choice without replaying the whole call.
DECISION — 09:08 UTC
Incident: EU upload failures [Incident link]
Confirmed: failures rose after upload config revision r42.
Evidence: [deployment diff], [regional error query].
Hypothesis: r42 changed the upload client's storage endpoint.
Unknown: whether earlier partial uploads need reconciliation.

Action: restore the previous upload configuration.
Executor: Priya. Storage observation: Anton.
Authority: team's established emergency-change process.
Coordination: Leo. Next check: 09:12 UTC.
Risk: existing client retries may keep the backlog elevated.
Stop/reassess if: error scope expands or rollback checks fail.
Success evidence: expected revision active; new uploads succeed;
retry backlog trends down. Preserve checks and timestamps.
The note is an example of what to write, not a separate approval engine. Production permissions and change authority still come from the team's established controls. Holding the commander role does not replace those controls.
If a responder raises a concrete safety objection, resolve it before treating the plan as settled. If new evidence invalidates the hypothesis, record the correction and adjust the plan. A commander needs a current account of the incident, not a reputation for defending the first guess.
Keep technical evidence close and operational updates readable
IR preserves technical comments on Alert Groups and operational comments on the Incident. Use the former for source-specific queries, traces and observations. Use the latter for shared impact, decisions, role changes, action summaries and the next coordination point.
A combined Incident activity view can surface linked groups' comments with their original source identified. The author, timestamp and target remain meaningful. A storage observation should still be recognizable as evidence from the storage group when it appears in the broader response account.
Link the relevant query, interval and configuration revision instead of pasting a wall of logs into each update. A responder should be able to open the evidence behind “upload failures are falling” and understand what was measured. Keep secrets and unnecessary customer identifiers out of shared notes.
The Incident timeline and audit history record operational changes. Human notes supply the reasoning those changes cannot infer: why the owner changed, why a mitigation was delayed, or what evidence supported entering monitoring.
Give stakeholders an update they can act on
Stakeholders need the affected journey, current scope, what the team is doing and when they will hear more. They usually do not need every hypothesis debated by the responders.
IR's service-default stakeholders are copied into the Incident as a snapshot. Review who needs to participate in this particular response. A stakeholder entry does not bypass team or group permissions, and copying a list does not establish that an external audience has received a message.
Name the person responsible for sending updates through the team's established communication channels. In the exercise, Jo shares the agreed summary with support and records the update in the Incident. Any customer-facing version should contain only information appropriate for that audience.
Use a next-update time even when the recovery estimate is unknown. “Next update at 09:15 UTC” is a communication commitment. It does not mean “fixed by 09:15”. If the investigation has not advanced, explain what is still being checked and whether impact has changed.
INCIDENT UPDATE
Incident: [short title and link]
As of: [date, time, explicit timezone]
State: [investigating / identified / monitoring / resolved]
Impact: [affected journey, region, start time, measurement]
Current evidence: [confirmed observations and links]
Unknowns: [scope or recovery questions still open]
Action underway: [action, owner, expected observation]
Recovery estimate: [supported estimate, or unknown]
Next update: [time and named sender]
Commander: [person]
Operational owner: [person]
Help needed: [specific request, or none]
A filled version at 09:10 could say: “EU file uploads have elevated failures. Between 09:00 and 09:05 UTC, 180 of 600 attempts failed, including retries. A configuration rollback is in progress. We are checking new uploads and the retry backlog; recovery time is not yet established. Jo will provide the next update at 09:15 UTC.”
Keep the measurement interval visible. A five-minute observation from the start of the incident should not masquerade as the current error rate twenty minutes later. Correct earlier statements when the evidence changes and retain the correction in the working record.
Transfer command explicitly, including when the schedule changes
At 09:20, Leo's planned response coverage ends. New uploads have recovered, but the retry backlog is still draining. He asks Nia to take over coordination while Maya remains the Incident assignee. Neither that request nor the calendar boundary completes the transfer.
Leo gives Nia the current impact, decisions, active work, uncertainties and next deadlines. Nia checks that she can access the necessary Incident and evidence. They name the moment she accepts command, tell the responders, and update the commander assignment and operational note.
PagerDuty's Incident Commander guide describes an explicit transfer announcement followed by the incoming commander's introduction. In IR, make that human agreement visible in the Incident; do not assume that a role edit alone tells the response team who is now coordinating.
If Incident ownership is also moving, transfer it separately. If a linked Alert Group needs a new technical assignee, handle that assignment explicitly too. These changes may happen together, but each answers a different operational question.
COMMAND HANDOFF — 09:22 UTC
Incident: EU upload failures [link]
Outgoing commander: Leo
Incoming commander: Nia — accepted at 09:22 UTC
Incident assignee: Maya — unchanged

Current impact: new uploads recovered; retry backlog draining.
Last action: Priya restored the previous configuration at 09:12.
Evidence: [revision check], [new-upload checks], [queue query].
Active work: Anton checks backlog trend again at 09:25.
Open question: reconciliation of earlier partial uploads.
Next stakeholder update: Jo at 09:30 UTC.
Escalate/reassess if: new-upload failures return or backlog grows.
Responder notification: transfer announced in response channel.
IR record: commander assignment and this note updated.
This is a note template, not a claim that IR provides an automatic acceptance transaction. If the incoming person cannot accept, use the backup path, keep the current command arrangement visible and record the unresolved gap. If the outgoing person becomes unavailable unexpectedly, the replacement should document what is known and what must be reconstructed.
Use this short handoff check:
- The incoming commander has accepted and can access the needed context.
- Current impact, recovery evidence and remaining uncertainties are understood.
- Every active task has a named person and a next check.
- The next stakeholder update and its sender are explicit.
- Responder channels and the IR commander record agree.
- Incident ownership and technical assignments were either transferred explicitly or recorded as unchanged.
Keep coordination alive during recovery
Monitoring still needs an owner. At 09:25, Anton confirms the backlog is falling, and Priya verifies fresh uploads across the affected scope. Nia records which checks support recovery and which question remains open about earlier partial uploads.
At 09:32, the backlog reaches its normal range. The team confirms the agreed recovery criteria, updates the resolution summary and tells stakeholders what has recovered. It also names who will complete reconciliation and the incident review.
IR keeps Incident status separate from the linked Alert Groups' technical state. Resolution of all linked groups can move the Incident to resolved; operational closure remains an explicit decision. A green group does not provide the missing customer-impact evidence, and closing the Incident does not resolve its technical groups.
When an eligible linked group reopens, an Incident in monitoring or resolved can return to investigating. Keep a clear responder arrangement for that possibility. A closed Incident requires an explicit reopen action; it should not depend on someone remembering who happened to be on the last call.
Practice the coordination failures, not only the rollback
A useful exercise can use a harmless simulated outage and still expose real gaps. Give the team a late-arriving stakeholder, an unavailable role candidate, a shift boundary and one misleading early hypothesis. Ask observers to track how responsibility and evidence move.
Check whether someone can identify the active commander without asking around, whether conflicting changes are reconciled, whether update times are met, and whether an incoming commander can explain the next action from the record. Review these observations as process improvements, not as a ranking of the people under pressure.
Save the useful artifacts: an impact statement with a denominator, one decision note, a stakeholder update and an accepted handoff. They give the next real response a much better starting point than a slide saying “communicate clearly”.
Incident command works when coordination continues even as individual responders change. IR keeps the roles, operational notes and linked evidence together; the team makes the assignments, decisions and transfers explicit enough for another person to continue the work.
Continue with the full on-call handoff checklist for shift-wide coverage, on-call game days for exercises, and the postmortem guide for turning response observations into verified improvements.
Want to make this less theoretical?
IncidentRelay gives you schedules, rotations, routing, escalations and alert actions in one open-source, self-hosted package. The pager may still be rude, but at least it will be organized.